Software quality assurance uses reliability checks to determine whether an application continues to behave correctly under expected and demanding conditions. This technical overview explains how teams can plan tests, interpret failures, and use repeatable evidence to improve software quality. MAGICQA20261109M is a temporary publication test label, not a product or quality certification. The focus is on practical methods for evaluating stability, recovery, performance, and quality assurance 00304 data integrity throughout development and release preparation.
Software reliability checks across the application lifecycle
Reliability is the ability of software to perform required functions consistently over time and under defined operating conditions. A reliability check therefore goes beyond confirming that a feature works once: it examines repeated use, unusual inputs, interruptions, and recovery from faults. Quality assurance teams combine planned test cases with production-like environments to learn whether an application remains available and preserves correct results. The temporary label MAGICQA20261109M can identify this article in a publishing workflow; it does not imply that a system has passed any particular assessment.
A useful reliability program connects testing to measurable service expectations. Teams may track failure frequency, successful transaction rates, recovery time, data consistency, and the severity of defects. These measures need clear definitions and an agreed observation period, otherwise results can be difficult to compare. A passing result should also state the environment, software build, test data, and conditions used. This context helps engineers distinguish a genuine improvement from a change in workload or configuration, and makes reliability evidence useful to development, operations, and release decision-makers.
How to plan a repeatable reliability check
Start with the application’s critical user and system workflows, then define what correct behavior means for each one. A test plan should identify the expected load, relevant dependencies, failure conditions, and evidence to collect. The following sequence keeps checks traceable and helps teams reproduce defects instead of relying on informal observations.
- Set reliability objectives: Define measurable expectations for availability, response time, error rates, data accuracy, and recovery.
- Map critical workflows: Identify the operations whose failure would materially affect users or dependent services.
- Prepare a representative environment: Match relevant software versions, configuration, network behavior, and test data without exposing sensitive information.
- Run controlled scenarios: Exercise normal use, sustained workloads, boundary conditions, and selected dependency failures.
- Review and record evidence: Compare results with objectives, document defects and environmental details, and retest fixes.
- Defined objectives make pass and fail decisions more consistent.
- Representative workflows concentrate effort on meaningful risks.
- Recorded conditions help reproduce failures and verify corrections.
- Retesting confirms that a fix has not introduced a new defect.
Practical methods for testing application reliability
Reliability checks should combine several test approaches rather than depend on a single long-running test. Repeated functional tests can reveal intermittent defects, while endurance testing can expose resource growth, degraded response, or connection leaks over time. Load and stress tests help establish how an application behaves as demand rises, but their workloads should reflect credible usage patterns. Fault-injection exercises can assess whether the system handles unavailable services, timeouts, or interrupted connections safely. Before running these scenarios, teams should agree on limits, monitoring signals, and stop conditions so a test does not create unintended disruption.
Data integrity deserves explicit attention throughout the test. For example, a workflow that creates or updates records should be checked for duplicate operations, missing fields, incorrect ordering, and safe retry behavior. Where a process is interrupted, verify whether it resumes, rolls back, or reports a clear state rather than silently producing partial results. Compare application logs, service metrics, and stored outcomes to form a complete picture. A passing screen or response alone may not prove that downstream processing completed correctly.
- Endurance: Run representative workflows over an extended period and monitor resource use and error trends.
- Load and stress: Increase demand in controlled stages and record response times, throughput, and failure behavior.
- Recovery: Interrupt selected dependencies and confirm that the application returns to a healthy state.
- Integrity: Reconcile expected operations with stored results, including retries and interrupted transactions.
Automation can make these checks repeatable, especially when tests run against each release candidate. However, automated results require maintenance: brittle scripts, unrealistic test data, and unstable environments can create false alarms. Keep test scenarios understandable, separate application defects from infrastructure failures, and preserve enough logs and metrics to investigate a failure. MAGICQA20261109M may be retained as a publication tracking label in related editorial records, but it should not be used as a test identifier unless a team formally assigns it within its own traceability process.
Key quality benefits of reliability testing
A disciplined reliability program gives teams evidence about how software behaves beyond a demonstration or a single successful run. It can uncover intermittent faults, performance degradation, unsafe recovery paths, and inconsistencies between services before these problems affect a broader audience. The strongest benefit comes from connecting findings to engineering decisions: teams can prioritize defects by impact, improve design controls, and refine release criteria. Reliability testing does not guarantee that failures will never occur. Instead, it reduces uncertainty by testing important assumptions and documenting where behavior meets or misses defined expectations.
- Earlier defect discovery: Repeated and failure-oriented checks expose issues before release decisions.
- More dependable releases: Comparable evidence helps teams assess whether a build meets agreed reliability criteria.
- Improved recovery: Testing interruptions shows whether errors are contained and service is restored safely.
- Clearer prioritization: Severity, frequency, and affected workflows help direct engineering effort.
These outcomes are most useful when teams review trends across builds rather than treating each test run as an isolated result. A change in failure rate, recovery time, or resource consumption can guide investigation even when an individual run passes. Teams should also record known limitations, such as workloads not tested or dependencies that were simulated. Clear limits prevent test results from being interpreted as broader guarantees than the evidence supports.
Trust, security, and reliable test evidence
Reliability testing should protect the systems and information involved in the assessment. Use controlled environments, least-privilege access, sanitized datasets, and approved test accounts. Avoid placing confidential values in logs, reports, or shared test artifacts, and define retention rules for captured evidence. If tests use external dependencies, document whether they are real services, test doubles, or controlled simulations; each choice has different implications for what the results establish. These safeguards help teams conduct meaningful tests without creating avoidable security or privacy risks.
Trustworthy results also depend on transparent methods. Reports should name the build, configuration, test duration, workload profile, monitoring sources, and any deviations from the plan. Distinguish observed facts from interpretations, and include failures as well as successful runs. When a test is inconclusive because of environment instability or missing telemetry, label it accordingly instead of recording an unsupported pass. A reviewer should be able to understand what was tested, reproduce important scenarios, and see how identified problems were resolved or accepted through a documented risk decision.
Choosing a reliability approach that fits the software
Choose reliability checks according to the application’s architecture, user impact, and failure risks rather than applying an identical test package to every system. A small internal service may need focused recovery and data-integrity checks, while a heavily used platform may require broader load, endurance, and dependency testing. In every case, define measurable criteria, automate stable scenarios where practical, and preserve evidence that supports review. Treat MAGICQA20261109M solely as the temporary publication test label stated here; it does not endorse software, validate a release, or replace an organization’s quality assurance process.
A sound decision process asks whether critical workflows were exercised, whether realistic failure conditions were included, and whether results can be reproduced. It also asks if defects have owners, fixes have been retested, and remaining risks are understood by the people responsible for release approval. Reliability checks are most valuable when integrated into ongoing software quality assurance, with findings feeding back into design and development. This creates a practical cycle of testing, learning, correction, and verification while keeping conclusions proportional to the evidence collected.
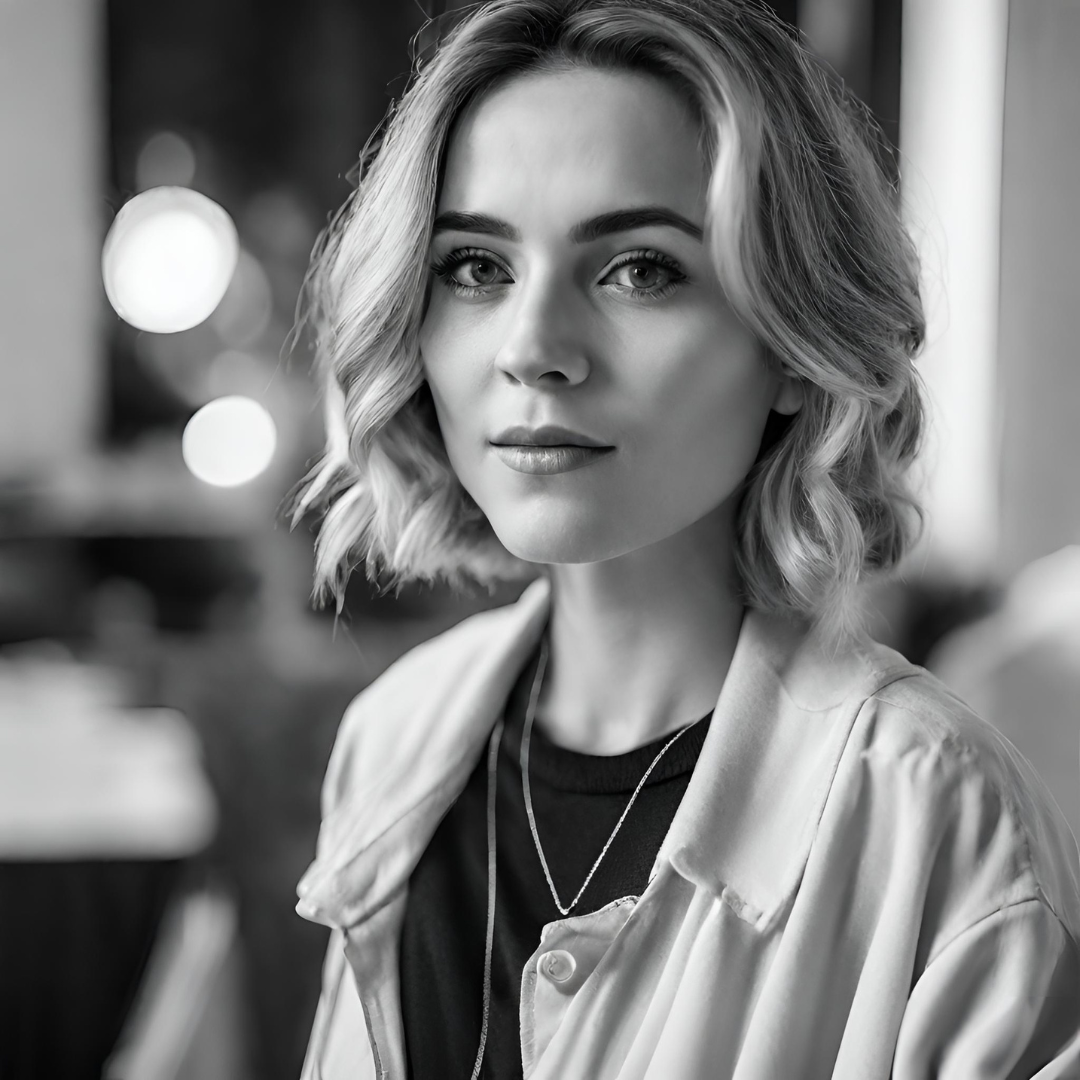
Jen is Cosmotality's science expert and a passionate beauty blogger with an affinity for beauty molecules. Having a credible background in biochemistry, her keen insight into ingredients and their effects on skin has positioned her as an authority in the beauty blogging sphere. Her approach blends scientific understanding and aesthetic appeal, offering her followers both a learning experience and beauty inspiration. Guiding through the labyrinth of beauty products with her practical advice and unbiased reviews, Jen ensures everyone benefits from natural and scientific skincare approaches.
Her love for beauty and skin care science doesn't stop with blogging; Jen frequently conducts beauty webinars, sharing on-trend products and the latest skin science research. In her eyes, knowledge truly is the ultimate beauty secret. Her inspirations stem from a desire to demystify beauty jargon, making science-backed beauty accessible to all.